The Network Is a Revenue Multiplier, Not a Cost Center
Ask most operators to rank where their AI infrastructure budget goes, and the network lands near the bottom — a line item to minimize, somewhere below GPUs, power, and cooling. It is treated as a cost to be managed rather than an asset that generates return.
For AI factories, that framing is not just outdated. It is expensive. The network is roughly 10 to 15 percent of total AI infrastructure spend, but when it runs properly it decides how much revenue the other 85 percent can actually produce. Get it right and it is a multiplier. Get it wrong and it quietly caps the return on the most expensive assets in the building.
At EPS Global, we work with the NeoCloud and sovereign operators living this reality, and the economics are hard to argue with once you see them. Here is why the network deserves a place in the revenue conversation — and how the right stack, assembled across the right partners, turns it into one.
The math that changes the argument
The metric that reframes everything is MFU — Model Flops Utilization, a measure of how much of your GPU capacity is actually doing useful work rather than waiting on the network.
The numbers are striking. A single percentage point of MFU improvement can translate into five to six percent more revenue for an operator, and can pay for the entire network several times over across its life. That is the whole case in one line: the network is a small slice of the budget with an outsized grip on output. Every gray failure, every bout of congestion, every stalled GPU is compute you paid for and did not sell.
This is why the network conversation is increasingly happening with CEOs, co-founders, and revenue leaders — not just network engineers. Once the network is understood as a revenue lever, minimizing its cost at the expense of its performance stops making sense.
Where the multiplier actually comes from
A revenue multiplier is not a single product. It is the compounding effect of getting every layer of the stack right, so GPUs stay busy and utilization stays high.
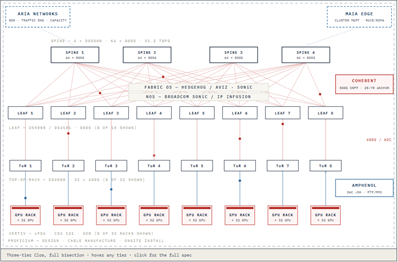
Keep the fabric lossless, and GPUs stay fed. AI east-west traffic punishes any congestion. Broadcom's Tomahawk 5 silicon at 51.2 Tbps, running on open hardware from Edgecore, Celestica, and UfiSpace, provides the raw capacity — and IP Infusion's OcNOS Data Center layers on RoCEv2, priority flow control, and dynamic load balancing to keep it congestion-free. A lossless fabric means fewer retransmissions, faster convergence, and GPUs computing instead of waiting. Broadcom Enterprise SONiC delivers the same performance with open-networking economics, supported by EPS Global as one of only two Broadcom SONiC support providers — with SONiC-based deployments associated with TCO reductions of up to 50 percent.
See problems before they cost you compute. You cannot recover revenue lost to a failure you never detected. Aria Networks pulls telemetry off the chip at microsecond resolution and uses AI to detect, discover, and resolve degradation across the whole fabric. Catching a gray failure early is the difference between a brief blip and hours of wasted, unbillable GPU time.
Onboard tenants and sites faster, and start earning sooner. Revenue does not begin until customers are connected. Maia Edge's Path Border Controller delivers private, AWS-style connectivity across distributed sites, so operators onboard tenants and link infrastructure in a fraction of the time that dark fiber and MPLS take. Hedgehog's cloud-native VPC layer lets operators offer a hyperscaler-like experience without a specialist fabric team — turning a private AI cloud into a service tenants can actually consume.
Move the traffic without loss. Utilization depends on the physical layer performing. EPS Global's 25-year partnership with Coherent supplies the pluggable optics and active optical cables that carry AI traffic, while Amphenol and Proficium deliver the high-density connectivity and infrastructure design that keep signal integrity high and installation clean at scale. EPS Global's range of coherent optics supports this layer of the stack.
Protect uptime with power and cooling. Throttled or unstable hardware is lost revenue. Vertiv's power and thermal-management infrastructure, together with the liquid and immersion cooling built into modern switches, keeps dense racks running at full performance rather than dialing back under thermal stress.
Each layer protects utilization. Together, they are what turns 10 to 15 percent of spend into a multiplier on the whole.
Why the right partner protects the return
Here is the risk. An operator can buy excellent components and still leave the multiplier on the table, because the return comes from the layers working together — not from any one box. A best-in-class switch behind a weak interconnect, or a fast fabric with no visibility into its own failures, does not deliver the utilization the economics promise.
That is the case for assembling the network as a validated stack. EPS Global brings Broadcom silicon, open hardware from Edgecore, Celestica, and UfiSpace, SONiC or OcNOS for the fabric, Aviz and Hedgehog for operations, Aria for visibility, Maia Edge for interconnect, Coherent optics, and Amphenol, Proficium, and Vertiv for the physical layer — validated together in our switch lab and delivered through one relationship, with global logistics and pre-sales engineering behind it. That integration is what protects the utilization the MFU math depends on.
It matters most for operators building inference infrastructure, who do not have hyperscaler-sized engineering teams to squeeze every point of MFU out of a fabric themselves. Partnering for a proven, integrated network frees their capital and their attention for what actually grows the business — and, as more than one operator has told us, lets them spend the savings on more GPUs and more network.
The operators who will win the AI buildout are the ones who stop asking how little they can spend on the network and start asking how much revenue it can unlock. Framed that way, the network is not the cost center at the bottom of the budget. It is one of the highest-leverage investments in the building.
Ready to treat your network as a revenue lever? Talk to EPS Global about a validated stack built to keep your GPUs earning.