Most conversations about AI infrastructure start and end with GPUs. Then power. Then cooling. The network usually comes up last, if at all — treated as plumbing that will sort itself out once the interesting decisions are made.
That order is backwards, and the operators who learn it the hard way pay for it in wasted compute. An AI cluster runs at the speed of its worst connection. It does not matter how many GPUs are in the building if the traffic between them, and between sites, stalls at a single weak link. As AI moves from centralized training toward distributed inference, that weak link is increasingly the one nobody planned for.
At EPS Global, we have watched this shift play out across the NeoCloud and sovereign operators we work with. Here is why connectivity has moved to the front of the design conversation — and how a validated stack, assembled across the right partners, keeps the whole system running at full speed.
Why the network moved to the front
Two forces are reshaping how AI infrastructure gets built.
The first is power. Available power caps how large any single site can be, so operators are forced to build in more locations wherever power exists. One data center becomes two, then several. Each new site multiplies the connectivity problem: you still need carrier access, but now the sites have to reach each other, and tenants have to reach all of them.
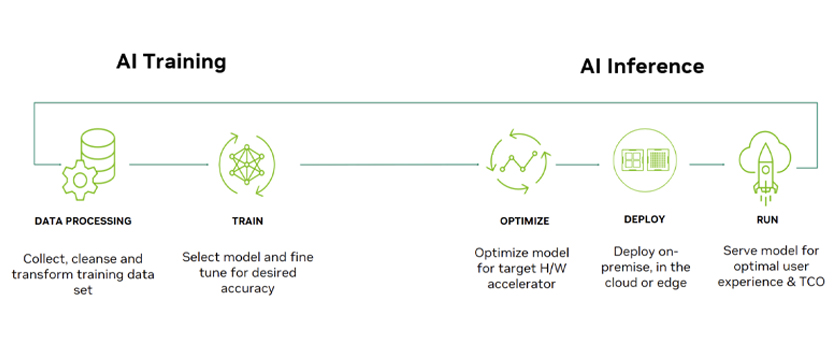
The second is the move from training to inference. Training tolerates a slightly imperfect network — a large, centralized cluster grinding through a job can absorb a little friction. Inference cannot. It is acutely sensitive to latency and has to sit physically closer to the users it serves, whether that is a hospital running AI-assisted surgery or a fleet of autonomous vehicles. Add agentic AI, where a single request might fan out across ten inference pods, and one poor connection or one wrong topology decision disrupts the entire workflow.
The result is an architecture with far more endpoints, spread across far more places, all of which have to interconnect cleanly. The network is no longer plumbing. It is the thing that determines whether the cluster earns its keep.
The connection is not one thing — it is every layer
"Your worst connection" is not a single cable. It is whichever layer of the stack is under-specified. A weak link can hide in any of them, which is why connectivity has to be designed as a system, not patched together component by component.
The fabric inside the cluster. East-west GPU traffic is unforgiving. Broadcom's Tomahawk 5 silicon at 51.2 Tbps underpins the Ethernet fabrics operators are building on open, ONIE-enabled hardware from Edgecore, Celestica, and UfiSpace. But raw switching capacity is only half the story — the fabric has to be lossless. IP Infusion's OcNOS Data Center delivers RoCEv2, priority flow control, and dynamic load balancing to keep the fabric congestion-free, while Broadcom Enterprise SONiC gives operators the same open-networking flexibility with production support from EPS Global, one of only two Broadcom SONiC support providers.
The optics and cabling that carry it. A fabric is only as good as the light moving through it. EPS Global has distributed Coherent optics for over 25 years, and demand for their pluggable transceivers and active optical cables has never been higher. Amphenol and Proficium complete the high-density interconnect, with Proficium engineering the connected-infrastructure design — floorplan, rack-and-row, and precise cable routing — so the physical layer does not become the bottleneck at scale.
The visibility to find the weak link before it costs you. Many operators cannot see gray failures, congestion, or degradation until compute is already being wasted. Aria Networks pulls telemetry off the chip at microsecond resolution and applies AI to detect and resolve issues across the entire fabric — NIC, transceivers, and switch. You cannot fix a worst connection you cannot see.
The link between sites. This is the layer that catches distributed operators off guard. Connecting two or more AI sites traditionally means carrier access to a meet-me room, then dark fiber or MPLS between locations, then VRFs, VLANs, or VXLANs to segment tenant traffic — slow to provision, costly, and complex. Maia Edge's Path Border Controller replaces that with private connectivity anywhere and an AWS-style direct-connect experience, so operators can link infrastructure and onboard tenants quickly. For private AI clouds that want a hyperscaler-like operating model without specialist fabric engineers, Hedgehog adds a cloud-native VPC layer on top.
The power and cooling that keep it stable. A connection is only as reliable as the environment around it. Vertiv's power and thermal-management infrastructure, alongside the liquid and immersion cooling built into modern switching hardware, keeps high-density racks from throttling — because a link that runs hot and unstable is a worst connection waiting to happen.
Designing connectivity as a system
The trap is optimizing one layer and assuming the rest will keep up. An operator buys the fastest switches, then discovers the site-to-site link cannot feed them. Or nails the interconnect, then loses compute to congestion they cannot see. The worst connection simply moves to whichever layer got the least attention.
This is exactly why EPS Global assembles these partners into a validated stack rather than shipping parts. Broadcom silicon, open hardware from Edgecore, Celestica, and UfiSpace, SONiC or OcNOS for the fabric, Aviz and Hedgehog for operations, Aria for visibility, Maia Edge for interconnect, Coherent optics, Amphenol and Proficium connectivity, and Vertiv power and cooling — tested together in our switch lab and delivered through one relationship, with global logistics and pre-sales engineering behind it.
The operators feeling this most acutely are the ones building inference, closer to the edge and further from the hyperscaler playbook. They do not have a hundred network engineers to hunt down weak links, and they should not need them. Get connectivity right as a system, and the network stops being the thing that limits the cluster and becomes the thing that lets it run flat out.
Your AI cluster will always run at the speed of its worst connection. The question is whether you designed that connection on purpose — or found it in production.
Planning a distributed AI buildout? Talk to EPS Global about designing connectivity as a system, from the fabric to the far site.